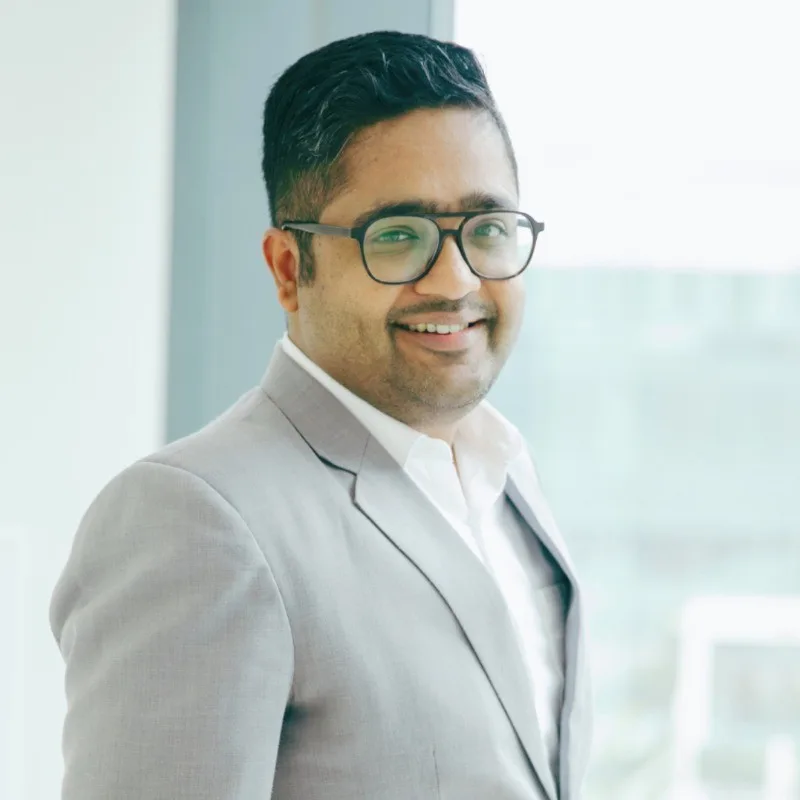
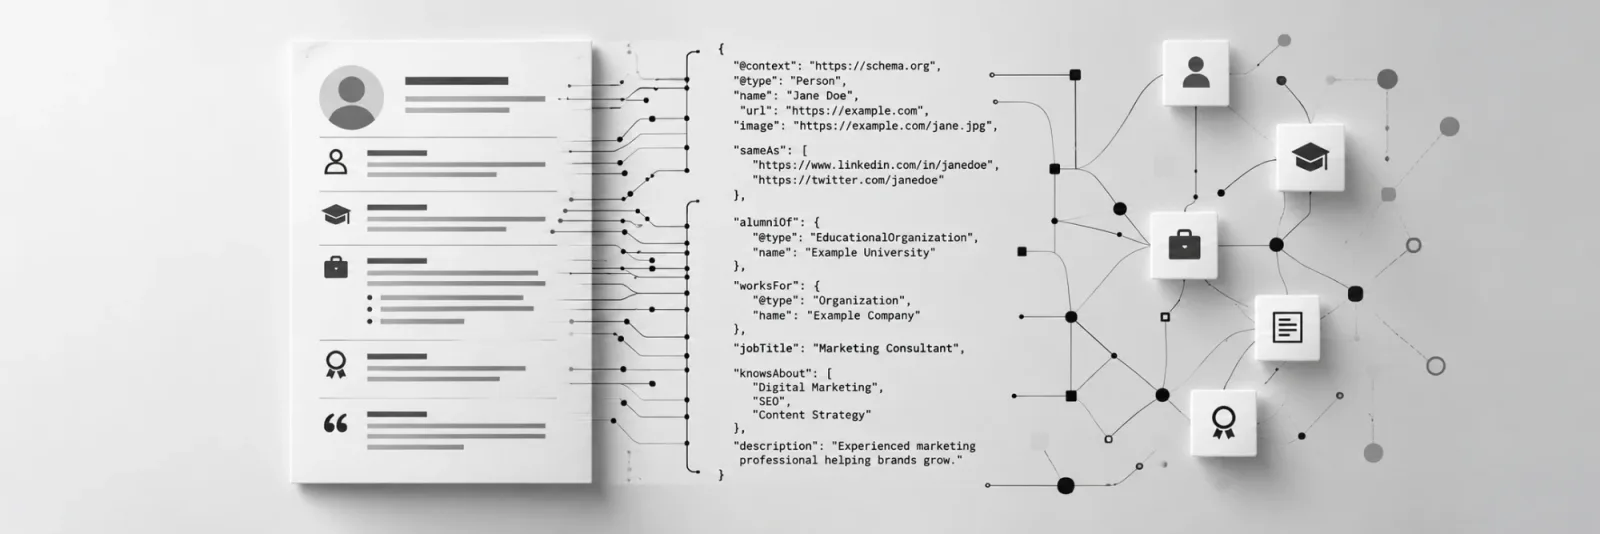
Schema markup is your website's resume, and for AI visibility that means both less and more than the hype suggests. It will not get you picked by ChatGPT or Google's AI on its own, and anyone selling it as an AI citation hack is overselling. What it does is make sure the machines screening you read the right name, the right credentials and the right references. A missing, vague or dishonest resume gets you screened out before the interview.
That is the argument. The rest of this essay explains what schema actually is, what the evidence says it does and does not do for AI visibility, and a five-line framework I use to decide which markup is worth the developer's time.
Key takeaways
Schema markup is a machine-readable summary of who you are and what a page is about. Think resume, not advert.
Google says there is no special schema needed for AI Overviews or AI Mode, and independent studies find no direct link between schema coverage and LLM citations.
Schema still earns its place upstream: it helps search indexes understand your entities, and those indexes feed the AI answers. Microsoft has said schema helps its LLMs understand content.
Prioritise five lines of your "resume": identity, references, credentials, offer and portfolio. Skip the rest until those are clean.
The one rule that never changes: never mark up anything you cannot back up on the visible page.
What is schema markup, in plain language?
Schema markup is a block of structured code on a web page that tells machines, in a fixed vocabulary, what the page is about. The vocabulary comes from Schema.org, a shared standard backed by the major search engines and a basic part of search engine optimisation. The most common format is JSON-LD, a small script that sits in the page and is invisible to human visitors.
Your page says, in prose, "Dr Sara Khan is a consultant cardiologist at our Dubai clinic." A human reads that easily. A machine has to guess: is Sara Khan a person, a clinic, a brand? Is "cardiologist" a job title or a department? Schema removes the guessing:
{
"@context": "https://schema.org",
"@type": "Physician",
"name": "Dr Sara Khan",
"medicalSpecialty": "Cardiovascular",
"worksFor": { "@type": "MedicalClinic", "name": "Example Clinic Dubai" },
"sameAs": ["https://www.linkedin.com/in/example-profile"]
}
An illustrative example with a fictional doctor and clinic.
Google's own documentation describes structured data as a way of "providing explicit clues about the meaning of a page". That phrase is the whole idea. Schema does not make your content better. It makes your content unambiguous.
Schema is not content. It is a statement about your content, in a language machines do not have to interpret.
Why "resume" is the right way to think about it
A resume does not do the job for you. It does something narrower and still decisive: it gets you correctly understood by someone screening hundreds of candidates in seconds. Name, role, credentials, references, relevant work. Structured, scannable, verifiable.
That is exactly the job schema does for a website, and the parallel holds further than it first appears:
A good resume...
Good schema...
Is read by a screener before a human ever sees you
Is read by crawlers and indexes before any AI answer is written
States facts in a predictable format
States facts in a shared vocabulary (Schema.org)
Lists references who can vouch for you
Uses sameAs to point to profiles that confirm who you are
Gets you binned if it is padded or false
Gets ignored, or penalised, if it describes content that is not on the page
Does not get you hired on its own
Does not get you cited on its own
Why "new"? Because the screener changed. For twenty years the main reader of your structured data was Google's results page, and the payoff was visible: star ratings, FAQ dropdowns, recipe cards. Now the reader is a stack of systems (search indexes, knowledge graphs, retrieval layers) that feed answers in AI Overviews, ChatGPT, Copilot, Perplexity and Gemini. The payoff is less visible. The screening is more important.
The old resume won you a prettier listing. The new one decides whether the machine knows who you are at all.
Does schema markup help AI visibility? What the evidence says
Not directly, and I think marketers should hear that before they hear anything else. Here is the opposing view, stated fairly: AI engines prefer clean, structured facts; schema is the cleanest structured fact on the page; therefore more schema means more citations. It is a tidy argument. It is also the pitch behind a lot of "AI schema" tooling. The evidence does not support it.
Google says no special markup is needed. Its documentation on AI features states: "There's also no special schema.org structured data that you need to add" to appear in AI Overviews or AI Mode. (Google Search Central)
Search Atlas found no correlation. Its domain-level analysis concluded that "schema markup does not influence how often LLMs cite web domains", with visibility nearly identical across all levels of schema adoption. (Search Atlas, updated June 2026)
Most AI platforms could not even read the markup directly. In OtterlyAI's three-month experiment on its own site (December 2025 to March 2026), only Gemini correctly retrieved the JSON-LD when asked; six of seven platforms failed. Citation changes after adding schema were mixed, up on some platforms and down on others. (OtterlyAI)
Two caveats on that evidence. Both studies come from vendors with their own products to sell, and OtterlyAI's is a single SaaS website. Neither proves schema is useless. They prove something narrower: schema is not a citation lever you can pull and watch move.
My read: if someone promises you AI citations from a schema project, ask them which platform, which query and which measurement. You will usually get a pause.
Schema works upstream, not at the answer
So why do I still put schema near the top of every AI search readiness audit? Because the AI answer is the last step in a chain, and schema does its work earlier in that chain.
Most AI search answers are grounded in a search index: the model retrieves pages, then writes. Those indexes, and the knowledge graphs behind them, are built by crawlers that do read structured data. Schema helps those systems resolve who you are, which entity a page describes and how your pages relate to each other. The model then inherits that understanding, whether or not it ever sees your JSON-LD.
There is also one first-party confirmation. At SMX Munich in March 2025, Microsoft's Fabrice Canel confirmed that schema markup helps Microsoft's LLMs understand content for Bing and Copilot. (Search Engine Land)
Put the pieces together and the honest position is this:
Schema does not make an AI choose you.
Schema reduces the chance an AI misunderstands you: the wrong address, the wrong doctor, the wrong service, a competitor's name blended with yours.
In categories where being misunderstood is expensive (healthcare, finance, anything with a physical location), that second point matters more than the first.
A resume does not get you hired. But a bad one gets you screened out before anyone reads your work.
This is also why I treat schema as the first of several layers, not the whole strategy. I wrote about the wider picture in AI search readiness, in plain language. Schema is the part that is mostly engineering. Authority and a distinctive editorial point of view do the rest.
The Five-Line Schema Resume
Schema.org has hundreds of types. Most websites need five things done well before they need anything else. I organise them the way a recruiter reads a resume, top to bottom.
Framework
The Five-Line Schema Resume
Identity: who you are, stated once, consistently, on every page that matters.
References: the external profiles that confirm you are who you say you are.
Credentials: the people behind the work, and why they are qualified.
Offer: what you actually do, sell or treat, and where.
Portfolio: your content, with authorship and dates a machine can trust.
Resume line
Core Schema.org types and properties
What the machine learns
Common mistake
Resume line
1. Identity
Core Schema.org types and properties
Organization, LocalBusiness or a specific subtype; name, logo, url, address
What the machine learns
Which entity this website belongs to
Common mistake
Three versions of the brand name across three templates
Resume line
2. References
Core Schema.org types and properties
sameAs links to official profiles (LinkedIn, Wikidata, Wikipedia, social, directories)
What the machine learns
That this entity is the same one described elsewhere
Common mistake
Missing entirely, or pointing to dead or unofficial profiles
Resume line
3. Credentials
Core Schema.org types and properties
Person or Physician; jobTitle, worksFor, alumniOf, hasCredential, medicalSpecialty
What the machine learns
Who is behind the expertise, and how they connect to the brand
Common mistake
Authors and experts exist only as names in the body copy
Resume line
4. Offer
Core Schema.org types and properties
Service, Product, Offer, areaServed; in healthcare, MedicalProcedure where it genuinely fits
What the machine learns
What you do, for whom, and where
Common mistake
Marking up services the page barely mentions
Resume line
5. Portfolio
Core Schema.org types and properties
Article or BlogPosting; author, datePublished, dateModified, publisher
What the machine learns
Who wrote it, for whom, and how current it is
Common mistake
dateModified updated on every deploy, whether or not anything changed
Source: author's framework. Type names from Schema.org.
Get these five right and you have a resume. Add anything else before them and you have decoration.
Never put anything on the resume you cannot defend in the interview
Every recruiter has met the candidate whose resume says "fluent in Arabic" and whose interview says otherwise. Search engines have met that website too.
Google's structured data guidelines are clear that markup must represent the content visible on the page, and that misleading or hidden markup can lead to a manual action. (Google Search Central)
The history of FAQ schema is the cautionary tale. It was used, then overused, to grab extra space on the results page. In 2023 Google restricted FAQ rich results to well-known government and health websites. In May 2026 it stopped showing them altogether. (Search Engine Journal) Teams who added FAQ markup purely for the visual payoff lost the payoff. Teams who used it to structure real questions their customers ask still have useful, well-structured pages.
Markup written to game a feature dies with the feature. Markup written to describe the truth outlives it.
What changes in healthcare
Healthcare is where I would push hardest on schema, for a simple reason: the cost of being misunderstood is higher. A patient asking an AI assistant for a paediatric cardiologist in Abu Dhabi needs the right doctor, at the right facility, with the right specialty. A blended or outdated answer is not a lost click. It is a lost patient, or a wrong visit.
Three things I check first on any hospital or clinic website:
Do doctor profile pages exist as entities? A Physician type with medicalSpecialty and a worksFor link to the facility, not just a name and a photo.
Does every branch have its own identity? Multi-location groups often mark up only the head office, leaving each clinic's address, hours and services to be guessed.
Does the markup match the listing ecosystem? If the schema, the Google Business Profile and the health directory all disagree on a doctor's specialty or a clinic's address, the machine has three references giving three answers.
Two guardrails. Schema should describe services and people, never make clinical claims the visible page does not make. And healthcare advertising rules in markets like the UAE apply to what the page says; markup does not get a separate, looser standard.
In healthcare, schema is less about being found and more about not being confused with someone else.
How to audit your schema resume in an afternoon
You do not need a platform to start. You need four tabs and some honesty.
Read the resume. Run your homepage, one service page, one people page and one article through the Schema Markup Validator. Note what types exist and what is missing against the five lines.
Check the Google view. Use Google's Rich Results Test and the enhancement reports in Search Console to catch errors on types Google still supports.
Call the references. Open every sameAs link. Is it live, official and consistent with the site on name, address and description?
Interview the machine. Ask ChatGPT, Gemini, Perplexity and Copilot the same plain questions: who is this brand, what does it do, where is it, who are its experts. Write down what is wrong or blended.
Trace the errors. For each wrong answer, ask whether your own site, markup or profiles are the source of the confusion. Fix those first; they are the ones you control.
What to do on Monday
Pick one canonical version of your organisation's name, logo and address, and make every template's Organization markup use it.
Add or fix sameAs on the organisation, pointing only to live, official profiles.
Mark up your top ten experts or authors as Person (or Physician) and connect them with worksFor.
Stop auto-updating dateModified on deploys. Change it when the content changes.
Delete any markup that describes something not visible on the page.
Where the resume metaphor breaks
Two places, and they are worth being honest about.
First, a human recruiter reads every resume. AI systems mostly do not read your JSON-LD directly; the evidence above suggests many cannot. Schema's influence is indirect, through the indexes and graphs those systems depend on. That makes it harder to measure, and it means you should not expect a before-and-after chart in six weeks.
Second, a resume is your main pitch. Schema is not. The things that make an AI cite you are the same things that make a person trust you: authority others grant you, and content with a point of view worth quoting. I have not seen a strong schema implementation rescue weak content, and I would be suspicious of anyone who claims they have.
Schema is necessary hygiene, not a growth strategy. Budget for it like hygiene: done properly, once, and maintained.
Frequently asked questions
01
What is schema markup in simple terms?
What is schema markup in simple terms?
Schema markup is structured code, usually JSON-LD, added to a web page to describe its content in a standard vocabulary from Schema.org. It tells search engines and other machines exactly what a page is about, such as an organisation, a doctor, a product or an article, so they do not have to infer it from the prose.
02
Does schema markup help with AI search visibility?
Does schema markup help with AI search visibility?
Indirectly. Google says no special schema is needed for AI Overviews or AI Mode, and independent studies have found no direct link between schema coverage and LLM citations. Schema helps search indexes and knowledge graphs understand your entities correctly, and those systems ground many AI answers. Microsoft has said schema helps its LLMs understand content.
03
Which schema types matter most for AI visibility?
Which schema types matter most for AI visibility?
Start with the basics that define identity and trust: Organization or a specific LocalBusiness subtype, sameAs links to official profiles, Person markup for authors and experts, Service or Product for what you offer, and Article with honest dates for content. Specialised types matter only once these five are accurate and consistent.
04
Should I remove FAQ schema now that Google no longer shows FAQ rich results?
Should I remove FAQ schema now that Google no longer shows FAQ rich results?
There is no need to rush. Google has said FAQ structured data can stay in place and will not cause problems, although it no longer produces a visible result in Google Search. Keep it where it describes real, visible questions and answers. Remove it where it was added only to win space on the results page.
05
Can schema markup hurt my website?
Can schema markup hurt my website?
Accurate schema does not hurt. Markup that describes content not visible on the page, or that misleads users, breaks Google's structured data guidelines and can lead to a manual action that removes rich result eligibility. The safe rule is simple: only mark up what a visitor can see and verify on that page.
Has schema ever moved your AI visibility in a way you could measure?
If you are seeing something different on your accounts, I would like to hear it. Evidence beats vendor decks.